
Building Blocks
Bloom Filters
Understanding bloom filters for space-efficient probabilistic membership testing.
2 min readConcepts · System Design
What is a Bloom Filter?
A Bloom Filter is a space-efficient probabilistic data structure that tests whether an element is a member of a set. It can have false positives but never false negatives.
Key Properties
| Property | Description |
|---|---|
| Space efficient | Much smaller than storing actual elements |
| False positives | May say "possibly in set" when not |
| No false negatives | "Definitely not in set" is always correct |
| No deletion | Standard bloom filters don't support removal |
How It Works
Structure
Bit Array (m bits, all start as 0):
┌─┬─┬─┬─┬─┬─┬─┬─┬─┬─┬─┬─┬─┬─┬─┬─┐
│0│0│0│0│0│0│0│0│0│0│0│0│0│0│0│0│
└─┴─┴─┴─┴─┴─┴─┴─┴─┴─┴─┴─┴─┴─┴─┴─┘
 0 1 2 3 4 5 6 7 8 9 ...

k hash functions: h1, h2, h3
Adding an Element
Add "apple":
  h1("apple") = 3
  h2("apple") = 7
  h3("apple") = 11

Set bits 3, 7, 11 to 1:
┌─┬─┬─┬─┬─┬─┬─┬─┬─┬─┬─┬─┬─┬─┬─┬─┐
│0│0│0│1│0│0│0│1│0│0│0│1│0│0│0│0│
└─┴─┴─┴─┴─┴─┴─┴─┴─┴─┴─┴─┴─┴─┴─┴─┘
       ↑       ↑       ↑
Checking Membership
Check "apple":
  h1("apple") = 3  → bit[3] = 1 ✓
  h2("apple") = 7  → bit[7] = 1 ✓
  h3("apple") = 11 → bit[11] = 1 ✓
  Result: Possibly in set

Check "banana":
  h1("banana") = 2  → bit[2] = 0 ✗
  Result: Definitely NOT in set
False Positive Example
Add "apple": bits 3, 7, 11
Add "grape": bits 5, 7, 14

Array after both:
┌─┬─┬─┬─┬─┬─┬─┬─┬─┬─┬─┬─┬─┬─┬─┬─┐
│0│0│0│1│0│1│0│1│0│0│0│1│0│0│1│0│
└─┴─┴─┴─┴─┴─┴─┴─┴─┴─┴─┴─┴─┴─┴─┴─┘

Check "mango" (never added):
  h1("mango") = 3  → 1 ✓
  h2("mango") = 5  → 1 ✓
  h3("mango") = 14 → 1 ✓
  Result: FALSE POSITIVE (says "maybe" but not in set)
Optimal Parameters
Given:
  n = expected number of elements
  p = desired false positive probability

Optimal bit array size (m):
  m = -(n × ln(p)) / (ln(2))²

Optimal number of hash functions (k):
  k = (m/n) × ln(2)

Example:
  n = 1,000,000 elements
  p = 1% false positive rate

  m ≈ 9.6 million bits (1.2 MB)
  k ≈ 7 hash functions
Implementation
import mmh3  # MurmurHash
from bitarray import bitarray

class BloomFilter:
    def __init__(self, size, num_hashes):
        self.size = size
        self.num_hashes = num_hashes
        self.bit_array = bitarray(size)
        self.bit_array.setall(0)

    def _hashes(self, item):
        """Generate k hash values for item"""
        for i in range(self.num_hashes):
            yield mmh3.hash(item, i) % self.size

    def add(self, item):
        """Add item to the filter"""
        for idx in self._hashes(item):
            self.bit_array[idx] = 1

    def contains(self, item):
        """Check if item might be in set"""
        return all(self.bit_array[idx] for idx in self._hashes(item))

    @classmethod
    def optimal(cls, n, p):
        """Create bloom filter with optimal parameters"""
        import math
        m = int(-(n * math.log(p)) / (math.log(2) ** 2))
        k = int((m / n) * math.log(2))
        return cls(m, k)

# Usage
bf = BloomFilter.optimal(n=1000000, p=0.01)
bf.add("user123")
bf.add("user456")

print(bf.contains("user123"))  # True (definitely or maybe)
print(bf.contains("user789"))  # False (definitely not)
Real-World Use Cases
| System | Use Case |
|---|---|
| Google Chrome | Safe browsing (malicious URL check) |
| Cassandra/HBase | Check if key exists before disk read |
| Medium | Check if user read an article |
| Akamai | One-hit-wonder cache filter |
| Bitcoin | SPV wallet transaction filtering |
Use Case: Database Optimization
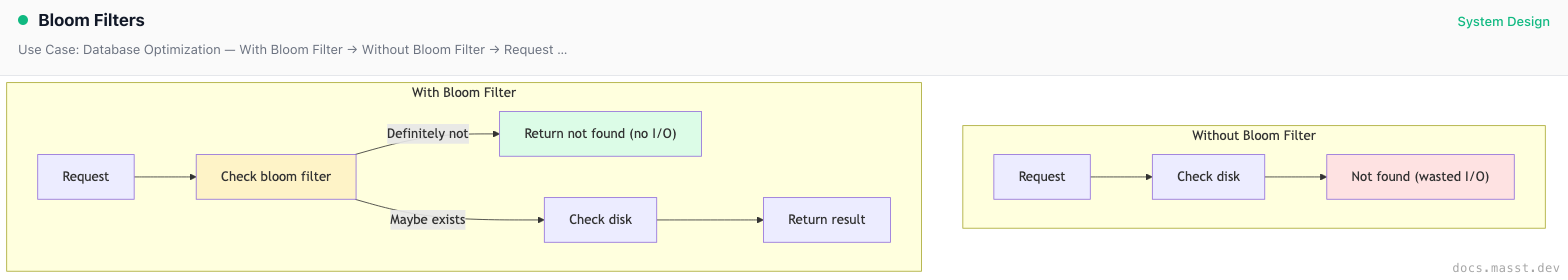
Savings: Avoid disk reads for non-existent keys.
Variants
| Variant | Feature |
|---|---|
| Counting Bloom Filter | Supports deletion (uses counters not bits) |
| Scalable Bloom Filter | Grows dynamically |
| Cuckoo Filter | Supports deletion, better space efficiency |
Interview Tips
- Explain false positive vs false negative
- Know the trade-off: space vs accuracy
- Mention real-world applications (Chrome safe browsing)
- Discuss when to use: membership testing before expensive operations
- Know limitations: no deletion, no element retrieval
Finished reading?
Mark it done to track your progress in Concepts.