
Eventual Consistency
Understanding eventual consistency in distributed systems and when to use it.
What is Eventual Consistency?
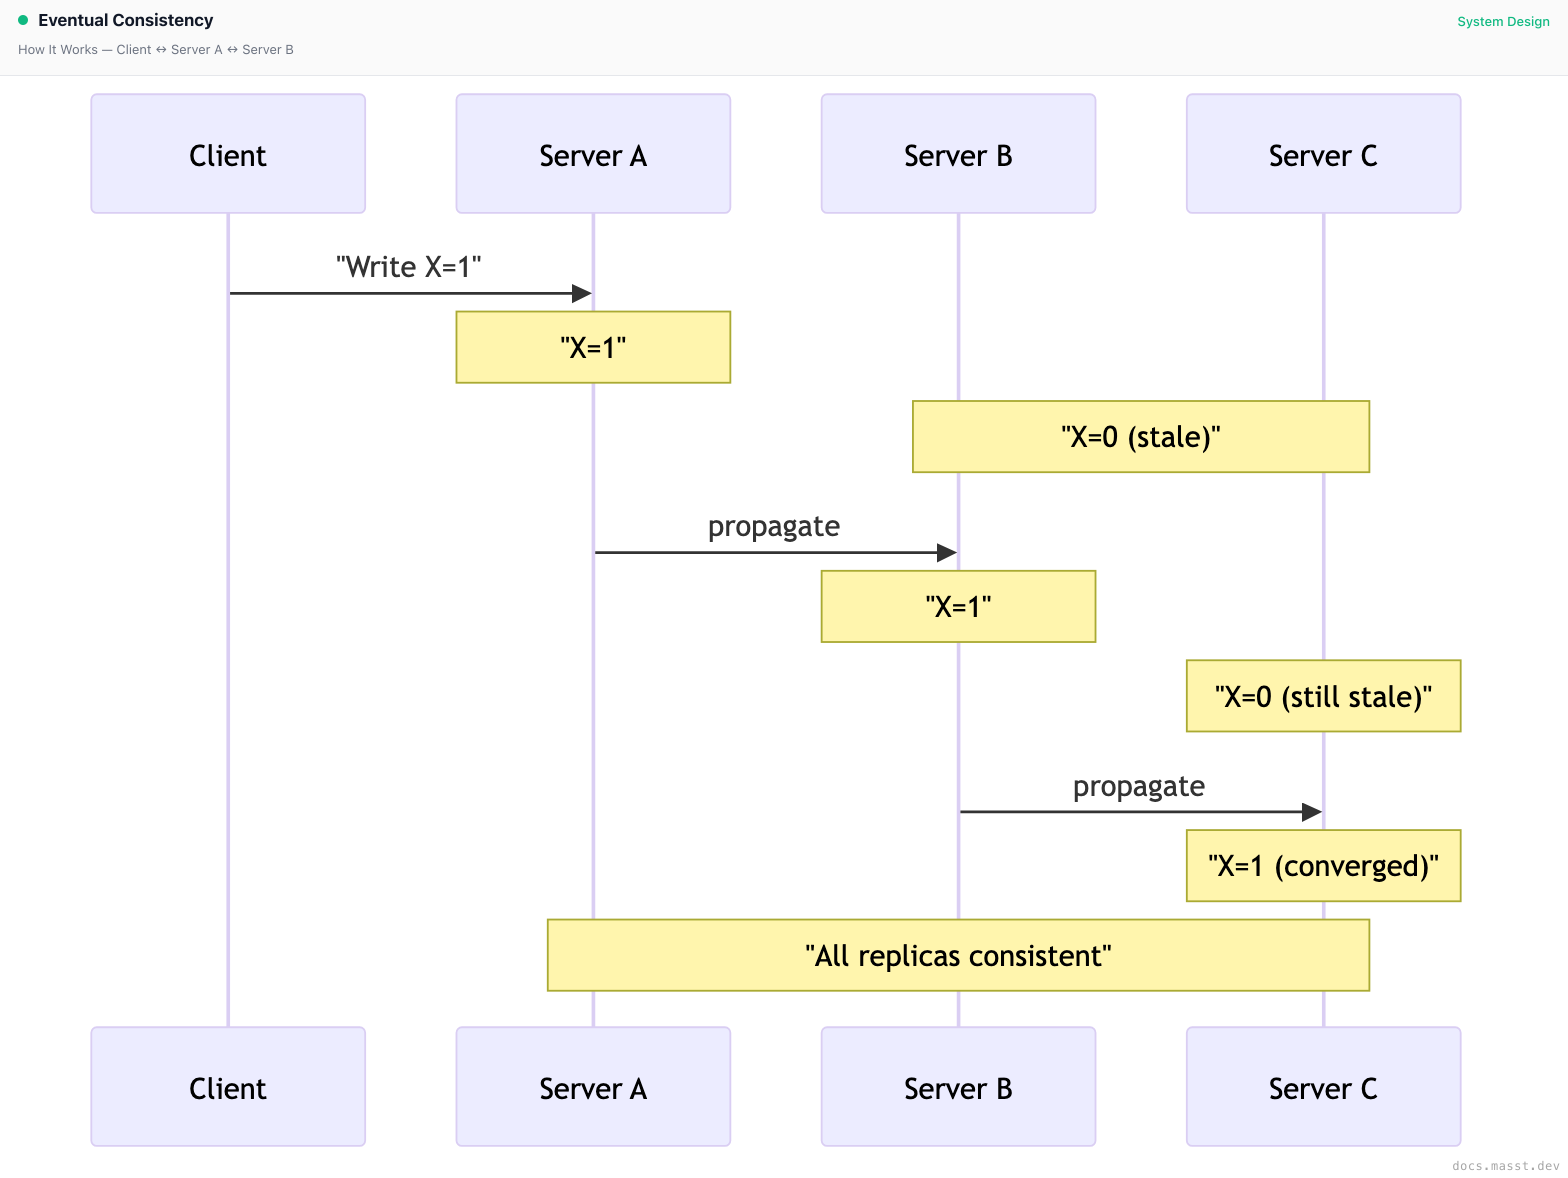
Eventual Consistency is a consistency model where, given enough time without new updates, all replicas will converge to the same value. It's the most common consistency model in large-scale distributed systems.
The Promise
"If no new updates are made to a given data item, eventually all accesses to that item will return the last updated value."
This means:
- Updates propagate asynchronously
- Temporary inconsistencies are allowed
- System will eventually become consistent
How It Works
Key Properties
| Property | Description |
|---|---|
| Convergence | All replicas eventually have the same data |
| Availability | System always responds to requests |
| Partition tolerance | Works during network partitions |
| No ordering | Updates may arrive out of order |
Consistency Window
The consistency window is the time between a write and when all replicas reflect it.
Factors affecting the window:
- Network latency between replicas
- Replication strategy (sync vs async)
- System load
- Geographic distribution
Typical windows:
- Same datacenter: milliseconds
- Cross-region: seconds to minutes
Conflict Resolution
When replicas receive updates in different orders, conflicts occur.
Last-Write-Wins (LWW)
Use timestamps to determine the "winner":
Server A receives: X=1 at T1, X=2 at T3
Server B receives: X=2 at T3, X=1 at T1

Final value on both: X=2 (T3 > T1)Problem: Clock synchronization issues can cause data loss
Version Vectors
Track causality to detect conflicts:
Server A: X=1 with vector [A:1, B:0]
Server B: X=2 with vector [A:0, B:1]

These are concurrent updates (neither happened before the other)
Conflict detected → application must resolve
CRDTs (Conflict-free Replicated Data Types)
Data structures that automatically merge without conflicts:
- G-Counter: Only increments, always mergeable
- PN-Counter: Increments and decrements
- G-Set: Grow-only set
- OR-Set: Add and remove from sets
- LWW-Register: Last-write-wins value
When to Use Eventual Consistency
Good Fit
| Use Case | Why |
|---|---|
| Social media feeds | Slight delays acceptable |
| Shopping carts | Availability > precision |
| User sessions | Can tolerate stale data briefly |
| Analytics | Aggregate trends matter more |
| DNS | Updates are infrequent |
Poor Fit
| Use Case | Why |
|---|---|
| Bank balances | Must be accurate |
| Inventory counts | Overselling is costly |
| Ticket booking | Double-booking unacceptable |
| Security permissions | Stale ACLs dangerous |
Real-World Examples
Amazon DynamoDB
- Default: eventually consistent reads
- Optional: strongly consistent reads (2x latency, 2x cost)
- Use case: Shopping cart persists across sessions
Apache Cassandra
- Tunable consistency levels
- QUORUM for stronger, ONE for faster
- Use case: Time-series data, user activity
DNS
- Classic eventual consistency example
- TTL-based propagation
- Updates take hours to propagate globally
Implementation Patterns
Read Repair
Fix inconsistencies during reads:
1. Read from multiple replicas
2. Compare values
3. If different, update stale replicas
4. Return most recent value
Anti-Entropy
Background process to synchronize replicas:
1. Periodically compare data between replicas
2. Use Merkle trees for efficient comparison
3. Sync only the differences
Hinted Handoff
Handle temporarily unavailable nodes:
1. Write intended for Node B
2. Node B is down
3. Store "hint" on Node A
4. When B recovers, A sends the hint
Trade-offs
| Advantage | Disadvantage |
|---|---|
| High availability | Temporary inconsistencies |
| Low latency | Complex conflict resolution |
| Partition tolerant | Hard to reason about |
| Scalable | Not suitable for all use cases |
Interview Tips
- Explain the window: Consistency happens over time, not instantly
- Discuss conflicts: How do you handle concurrent updates?
- Know real systems: DynamoDB, Cassandra, DNS examples
- Mention CRDTs: Show awareness of advanced techniques
- Trade-offs: Availability and latency vs consistency
Summary
Eventual consistency is the backbone of large-scale distributed systems. It sacrifices immediate consistency for:
- Higher availability: Always respond to users
- Lower latency: Don't wait for all replicas
- Better partition tolerance: Work through network issues
The key is understanding your application's tolerance for temporary inconsistency and implementing proper conflict resolution strategies.
Finished reading?
Mark it done to track your progress in Concepts.